
Proxy Knowledge
Guide to Configuring Rotating Proxies in Python for Web Scraping Without Getting IP Banned

Table of contents
1. Problem Statement: Why Does Web Scraping Get Your IP Banned?
In the digital age, web scraping has become an essential tool for businesses, researchers, and developers. Data from e-commerce websites, social networks, or news portals delivers immense commercial value. However, when you perform large-scale data collection, web defense systems will quickly detect abnormal behaviors.
Modern web servers are equipped with powerful defense mechanisms such as WAF (Web Application Firewall), Cloudflare, Akamai, or Imperva. One of the most common control methods is Rate Limiting. When an IP address sends too many requests within a short timeframe, the system automatically flags that IP as suspicious and takes action:
- Returns HTTP status code 429 (Too Many Requests) or HTTP 403 (Forbidden).
- Displays CAPTCHA challenges (reCAPTCHA, hCaptcha, Turnstile).
- Blocks the connection entirely (IP Ban / IP Block) permanently or temporarily.
To fundamentally solve this problem, using a rotating proxy python configuration is the leading solution to hide your server's identity, simulate access from thousands of real users, and ensure your data scraping process runs continuously without interruption.
2. What Is a Rotating Proxy and How Does It Work?
A proxy acts as an intermediary server sitting between your Python application and the target website. When you send an HTTP request through a proxy, the target website sees only the proxy server's IP address rather than your real IP address.
Basic Proxy Classification: Datacenter IP vs. Residential IP
Before diving into technical python proxy configuration, you need to distinguish between two common types of proxies:
- Datacenter Proxy: IPs generated from data centers (AWS, DigitalOcean, Hetzner, etc.). The main advantages are fast speeds and low costs. However, a major drawback is that they are easily detected by anti-bot systems because the IP ranges do not belong to residential Internet Service Providers (ISPs).
- Residential Proxy: Real IP addresses assigned by ISPs (VNPT, Viettel, AT&T, Comcast, etc.) to home users. This is the most trustworthy type of proxy and is extremely hard to block, though costs are higher.
Mechanism of Rotating Proxies
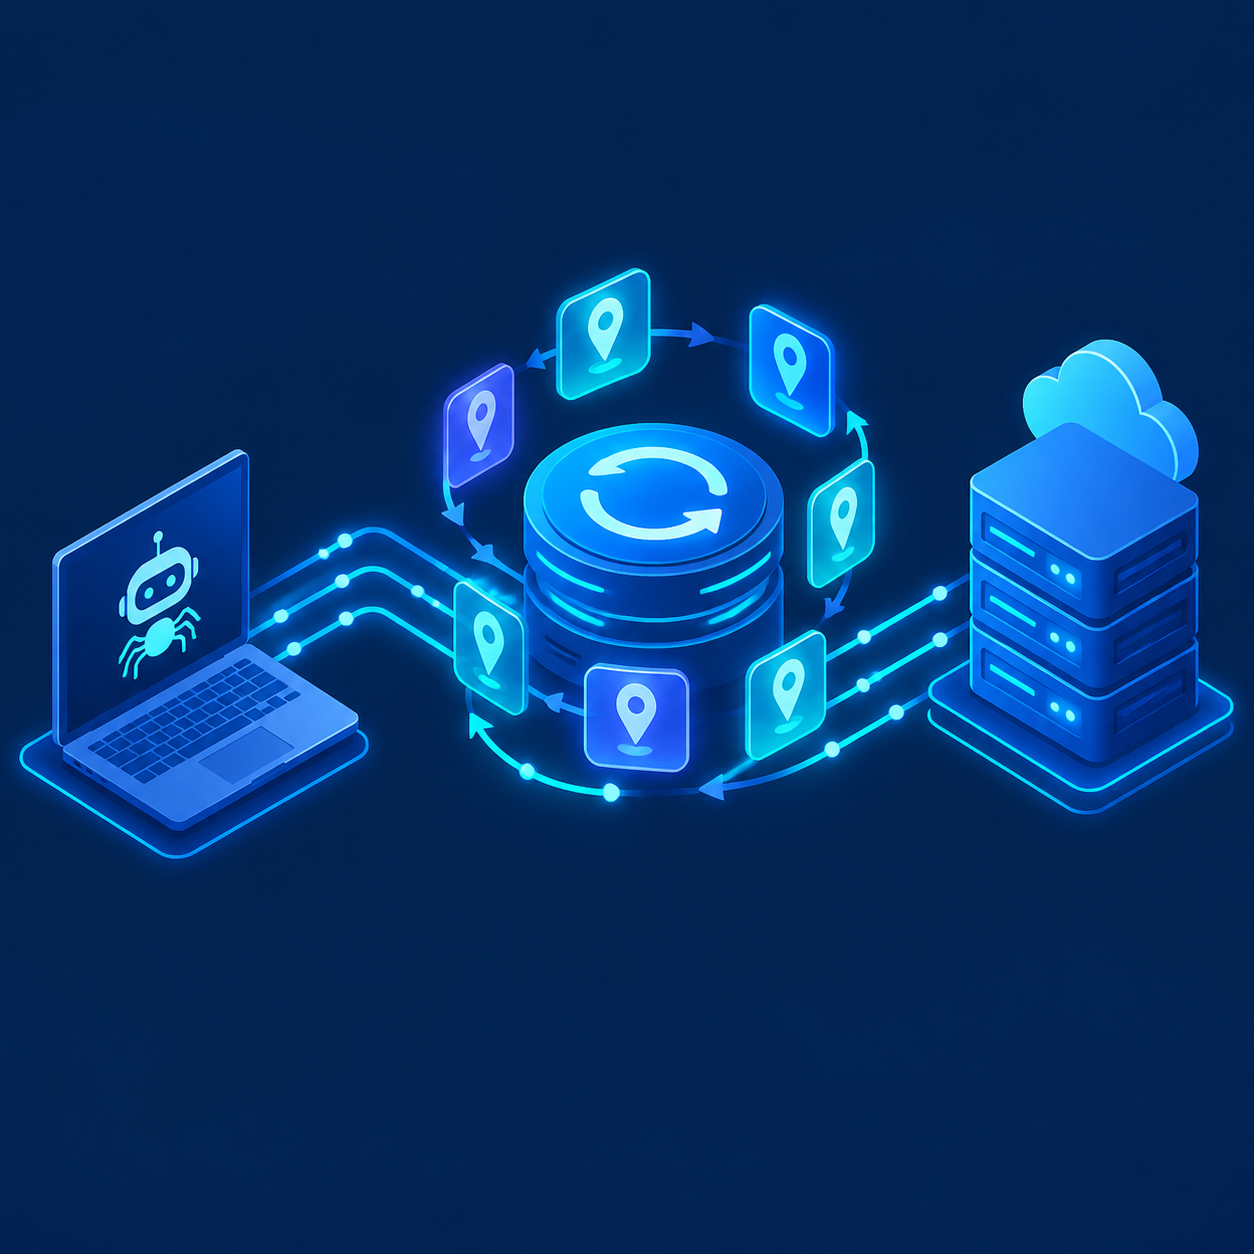 Rotating proxies dynamically route each web request through a different IP address from a large IP pool.
Rotating proxies for scraping automatically change IP addresses after every HTTP request or after a specified duration (a few minutes). Instead of using a single IP for thousands of requests, the system continuously rotates through a pool containing millions of different IPs. As a result, the target website views each of your requests as a completely new visitor, dismissing automation suspicions and optimizing your IP ban prevention while scraping.
3. Guide to Configuring Rotating Proxies with Python Requests
The requests library is the standard and most popular tool in Python for working with HTTP requests. Below are methods to set up a python requests proxy from basic to professional levels.
Method 1: Configuring a Single Proxy in Requests
To understand the working principle, you first need to understand how to pass a proxy to a request object in Python. The requests library supports a keyword parameter named proxies that takes a dictionary containing IP and Port information.
import requests
proxies = {
'http': 'http://10.10.1.10:8080',
'https': 'http://10.10.1.10:1080',
}
response = requests.get('https://httpbin.org/ip', proxies=proxies)
print(response.json())
If your proxy requires Username and Password authentication, you can format the URL string as: http://user:password@host:port.
Method 2: Building a Custom Manual Proxy Rotator
If you have a list of static IPs (Proxy list), you can randomly select an IP for each request using Python's random library.
import requests
import random
proxy_list = [
'http://user:[email protected]:8080',
'http://user:[email protected]:8080',
'http://user:[email protected]:8080'
]
def get_with_random_proxy(url):
proxy = random.choice(proxy_list)
proxies = {'http': proxy, 'https': proxy}
try:
response = requests.get(url, proxies=proxies, timeout=5)
return response
except requests.exceptions.RequestException as e:
print(f'Proxy {proxy} error: {e}')
return None
Although this manual solution is simple, it has drawbacks: You must manage the IP list yourself, filter dead proxies manually, and the list size is typically limited.
Method 3: Using a Professional Rotating Proxy Service (Recommended)
Professional proxy providers (such as Bright Data, Oxylabs, Smartproxy, GeoSurf) offer a single entry point (Single Endpoint Gateway). You only need to connect to this Endpoint, and the provider's backend system will automatically rotate IPs for you on every request.
import requests
proxy_endpoint = 'http://username:[email protected]:7000'
proxies = {
'http': proxy_endpoint,
'https': proxy_endpoint
}
for i in range(5):
res = requests.get('https://httpbin.org/ip', proxies=proxies)
print(f'Attempt {i+1} - Displayed IP:', res.json()['origin'])
With this approach, you don't need to worry about IP selection or handling broken IPs, keeping your Python source code much cleaner and more stable.
4. Configuring Rotating Proxies in the Scrapy Framework
For extremely large-scale data collection projects, Scrapy is the leading framework thanks to its asynchronous architecture. To integrate a rotating proxy python setup into Scrapy, we can use the extension library scrapy-rotating-proxies.
Step 1: Install the Library
You can install the extension package using the pip command:
pip install scrapy-rotating-proxies
Step 2: Configure settings.py in Your Scrapy Project
Open the settings.py file of your Scrapy project and add the following Middleware configuration lines:
DOWNLOADER_MIDDLEWARES = {
'scrapy_rotating_proxies.middlewares.RotatingProxyMiddleware': 610,
'scrapy_rotating_proxies.middlewares.BanDetectionMiddleware': 620,
}
Next, declare your list of proxy IPs or the path to your rotating proxy Endpoint in settings.py:
ROTATING_PROXY_LIST = [
'http://user:[email protected]:8000',
'http://user:[email protected]:8000',
'http://user:[email protected]:8000',
]
The scrapy-rotating-proxies library will automatically monitor the health of each proxy. If a proxy returns an error (403, 429, or Timeout), the library will automatically mark that IP as banned and redirect the request to another healthy IP.
5. High-Speed Performance Optimization with Asyncio and Aiohttp
 Asynchronous web scraping enables sending hundreds of concurrent requests through rotating proxies without delay.
When you need to send thousands of requests per minute, using requests (synchronous) can become a speed bottleneck. Combining asyncio and aiohttp with rotating proxies will boost your crawler speed exponentially.
import asyncio
import aiohttp
proxy = 'http://user:[email protected]:8080'
urls = ['https://httpbin.org/ip' for _ in range(10)]
async def fetch(session, url):
try:
async with session.get(url, proxy=proxy, timeout=10) as response:
json_data = await response.json()
print('Retrieved IP:', json_data.get('origin'))
except Exception as e:
print('Connection error:', e)
async def main():
async with aiohttp.ClientSession() as session:
tasks = [fetch(session, url) for url in urls]
await asyncio.gather(*tasks)
asyncio.run(main())
6. Best Practices for Preventing IP Bans When Web Scraping
Using rotating proxies for scraping is necessary, but not sufficient to guarantee 100% success for your web scraping campaign. Modern anti-bot systems analyze many factors beyond IP addresses. Here are battle-tested practices to boost your success rate:
6.1. Rotating Headers and User-Agents
 Rotating User-Agents alongside IP rotation conceals automated scraper traffic under authentic browser profiles.
The User-Agent is an identification string representing the browser and operating system sent to the server. If thousands of different IPs send the default Python User-Agent string (e.g., Python-requests/2.31.0), systems will instantly detect it as a bot.
- Use the fake-useragent library to generate random User-Agent strings from popular browsers (Chrome, Firefox, Edge, Safari on both Desktop and Mobile).
- Ensure that other critical HTTP Headers like Accept-Language, Accept-Encoding, and Sec-Ch-Ua are declared completely and logically.
6.2. Controlling Request Rates and Introducing Delays
Sending continuous requests without delays overloads target servers and gets flagged easily. Introduce random pause intervals between requests (e.g., waiting 1 to 3 seconds) using time.sleep(random.uniform(1, 3)) in Python.
6.3. Handling Cookies and Sessions
Many websites track user behavior using cookies. When using rotating proxies, clear cookies or initialize a new Session for requests sent through a new IP to prevent systems from linking different IPs to the same suspicious session.
6.4. Headless Browsers with Selenium or Playwright
For websites rendering dynamic content via JavaScript (SPA, React, Vue), simple HTTP requests might fail to retrieve data. You should combine Playwright or Selenium in Headless mode while integrating proxy extensions or parameters to simulate mouse movements/scrolling while safely rotating IPs.
7. How to Choose the Best Rotating Proxy Provider
To select the right python proxy configuration service, consider criteria such as IP pool size, request success rates, response speeds, and geographic targeting (Geo-targeting) support.
- Bright Data (Luminati): The world's largest provider with over 72 million residential IPs. Feature-rich with ultimate reliability, though prices are high, making it best suited for large enterprises.
- Oxylabs: A direct competitor to Bright Data, renowned for lightning-fast response times and comprehensive API documentation for Python developers.
- Smartproxy: A balanced choice between cost and quality. Easy setup, good technical support, suitable for both personal projects and small-to-medium businesses.
- IPRoyal: Offers non-expiring residential proxy traffic packages at competitive pricing, making it very beginner-friendly.
8. Conclusion
Mastering rotating proxy python techniques is the deciding factor in the success of any large-scale web scraping project. By flexibly combining residential IP rotation, smart User-Agent rotation, and proper request rate control, you will build a powerful, resilient data crawling system without worrying about anti-scraping IP ban barriers.
Start applying the sample code snippets from this article to your projects today to feel the difference in speed and scraping success rates!
Related articles
Ready for real proxies, not just the guide?
Buy Residential, ISP, Datacenter, or Mobile proxies — live in minutes.
View products