
Proxy Knowledge
Guide to Configuring Datacenter Proxies for High-Speed Enterprise Web Scraping

Table of contents
Introduction to Datacenter Proxies in Large-Scale Web Scraping
In the digital era, data is considered an invaluable resource that helps businesses make informed strategic business decisions. However, large-scale web scraping often encounters barriers from advanced anti-bot mechanisms on target websites. To address this challenge, using datacenter proxies has become a top choice thanks to superior processing speed and cost optimization.
This article provides a detailed guide on how to configure datacenter proxies to achieve high-speed web scraping performance, helping your enterprise's data crawler proxy system run smoothly and stably.
Why Choose Datacenter Proxies for Enterprise Web Scraping?
Datacenter proxies are IPs provided by independent data centers, unaffiliated with residential internet service providers. Compared to residential proxies, this type of proxy offers distinct competitive advantages:
- Superior Speed and Bandwidth: Thanks to data center network infrastructure, latency is extremely low and stability is high, making it perfectly suited for high-speed web scraping projects.
- Cost Optimization: The cost of datacenter IPs is significantly lower than residential IPs when enterprises need to make millions of requests daily.
- Easy Scalability: Enterprises can quickly acquire and manage thousands of IP addresses to serve large-scale data collection campaigns.
Step-by-Step Guide to Configuring Datacenter Proxies for Maximum Performance
To build an efficient data crawler proxy infrastructure, correct technical setup is a decisive factor. Below are the detailed steps to properly configure datacenter proxies.
1. Choose the Right Connection Protocol (HTTP/HTTPS vs SOCKS5)
Each connection protocol provides different efficiency depending on the data collection goal:
- HTTP/HTTPS Proxy: Suitable for standard web scraping. This protocol allows easy manipulation and customization of HTTP headers such as User-Agent, Cookie, or Referer.
- SOCKS5 Proxy: The optimal choice when higher performance is needed, supporting flexible data transmission and superior security at the transport layer.
2. Set Up IP Rotation Mechanisms
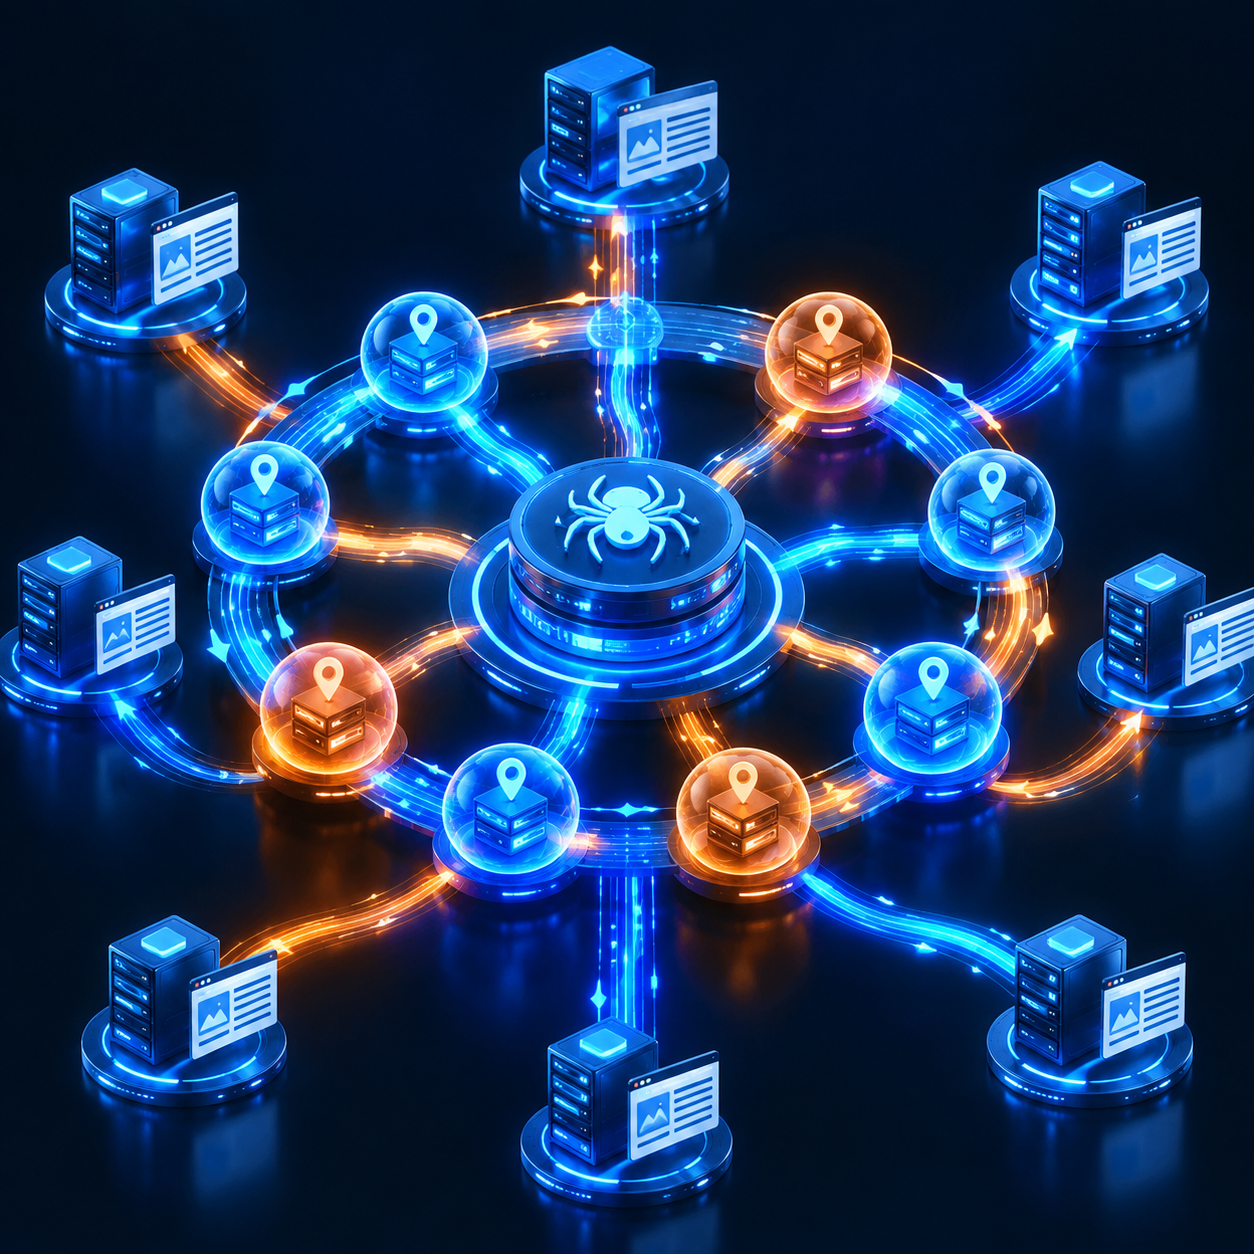 An automated IP rotation mechanism dynamically switches proxy addresses from a central pool to prevent IP blocking.
Modern websites often track the number of requests from a single IP address. Sending too many requests in a short period will inevitably get your IP banned. The solution is to apply IP rotation techniques:
- Per-Request Rotation (Random Rotation): Each outgoing request uses a random IP from the proxy pool. This technique is extremely effective when scraping websites that do not require login.
- Session-Based Rotation: Keeps a single IP for a specified period (e.g., 5-10 minutes) to complete a workflow before switching to a new IP.
3. Manage Request Headers and Simulate Browsers
No matter how fast a datacenter proxy address is, it is easily detected if it sends requests with default headers from scraping libraries (such as Python Requests or Axios). Therefore, enterprises need to:
- Generate a diverse list of User-Agent headers representing popular browsers on both desktop and mobile devices.
- Dynamically alter other headers such as Accept-Language and Accept-Encoding to mimic real users.
4. Handle Rate Limiting and Implement Reasonable Delays
Although the goal is high-speed web scraping, sending requests too aggressively will crash the target server or trigger security firewalls. Set up a random delay of 0.5 to 2 seconds between requests to minimize the risk of detection.
5. Build an Automated Error Handling and Retry System
A data crawler proxy system needs an automated mechanism to log HTTP error codes (such as 403 Forbidden, 429 Too Many Requests). Upon encountering these errors, the system should:
- Automatically remove the failing IP address from the active pool temporarily.
- Retry sending the request using another datacenter proxy IP from the backup list.
Solutions to Overcome Datacenter Proxy Limitations
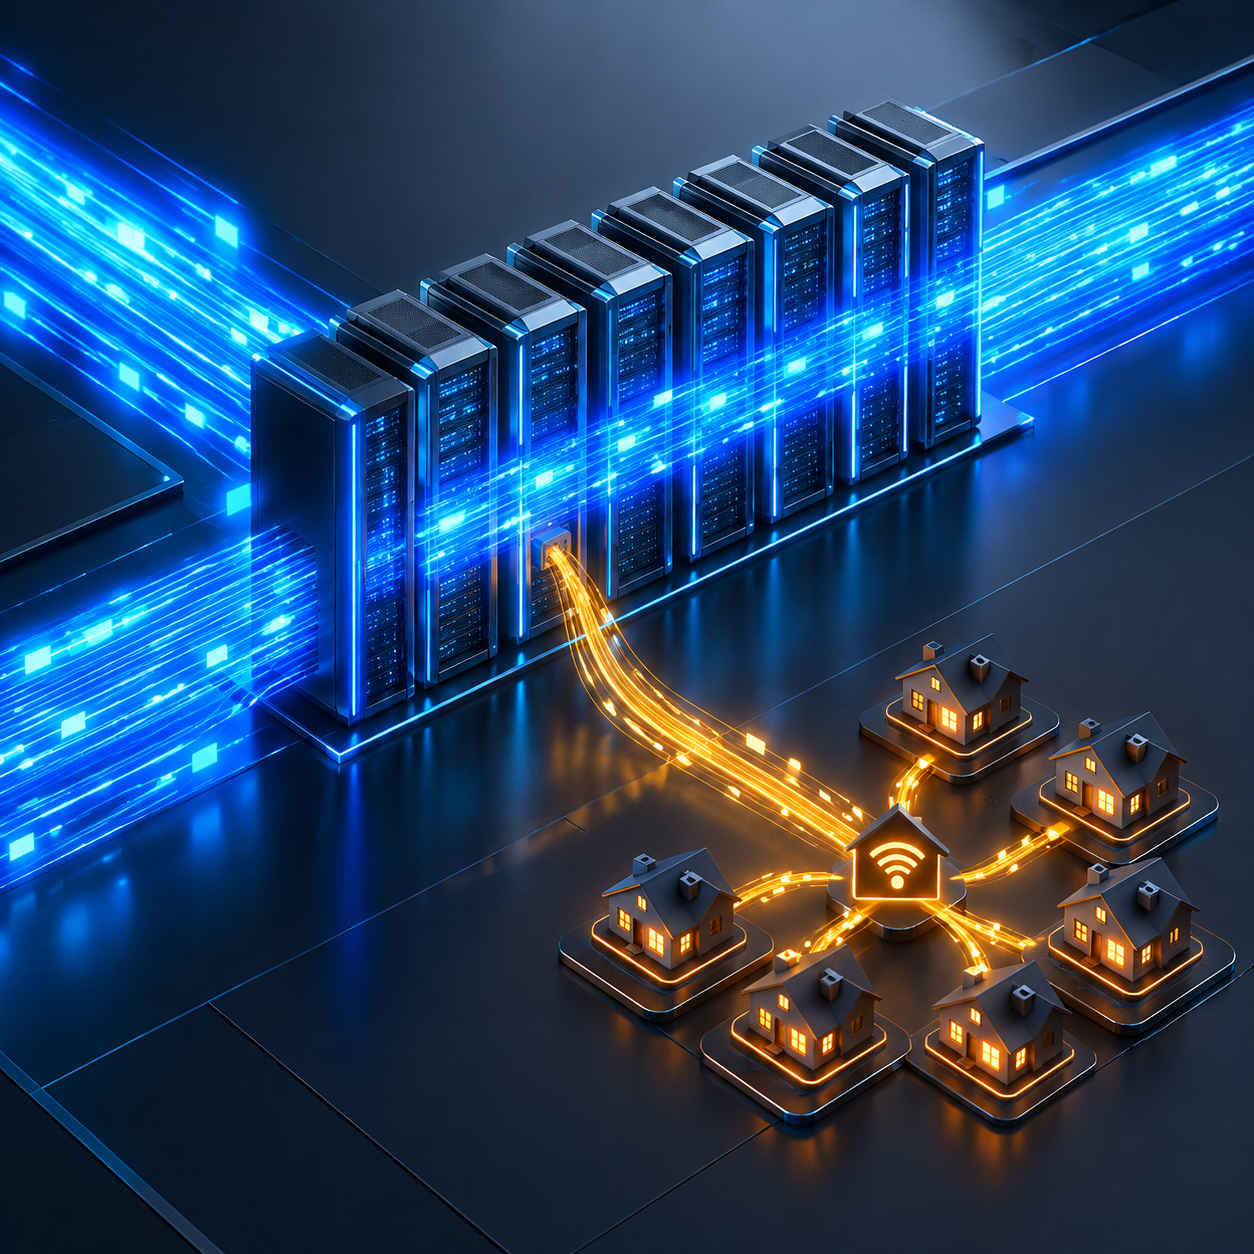 Enterprise hybrid proxy architecture relies on datacenter proxies for primary high-speed scraping while routing sensitive requests through residential IPs.
The biggest drawback of datacenter IPs is that they are easily identified by advanced anti-bot systems because datacenter IP ranges are often publicly declared. To overcome this, enterprises should adopt a flexible hybrid strategy:
- Use datacenter proxies for 80-90% of regular websites or static data to save costs and maximize speed.
- Automatically route requests to Residential Proxies only when encountering websites with strict security mechanisms or complex Captcha challenges.
Conclusion
Technically sound datacenter proxy configuration is the key to helping enterprises master large-scale data collection. With fast response capabilities and cost optimization, a data crawler proxy system utilizing datacenter proxies will deliver superior efficiency for high-speed web scraping operations.
Start by selecting a reputable proxy provider, combined with flexible IP rotation solutions and intelligent request management to ensure your business data flow remains uninterrupted.
Related articles
Ready for real proxies, not just the guide?
Buy Residential, ISP, Datacenter, or Mobile proxies — live in minutes.
View products